Avoiding Sampling Bias in Market Research
Sampling bias skews findings when participants don't reflect the population. Learn what causes it and how to build a sampling plan that avoids it.

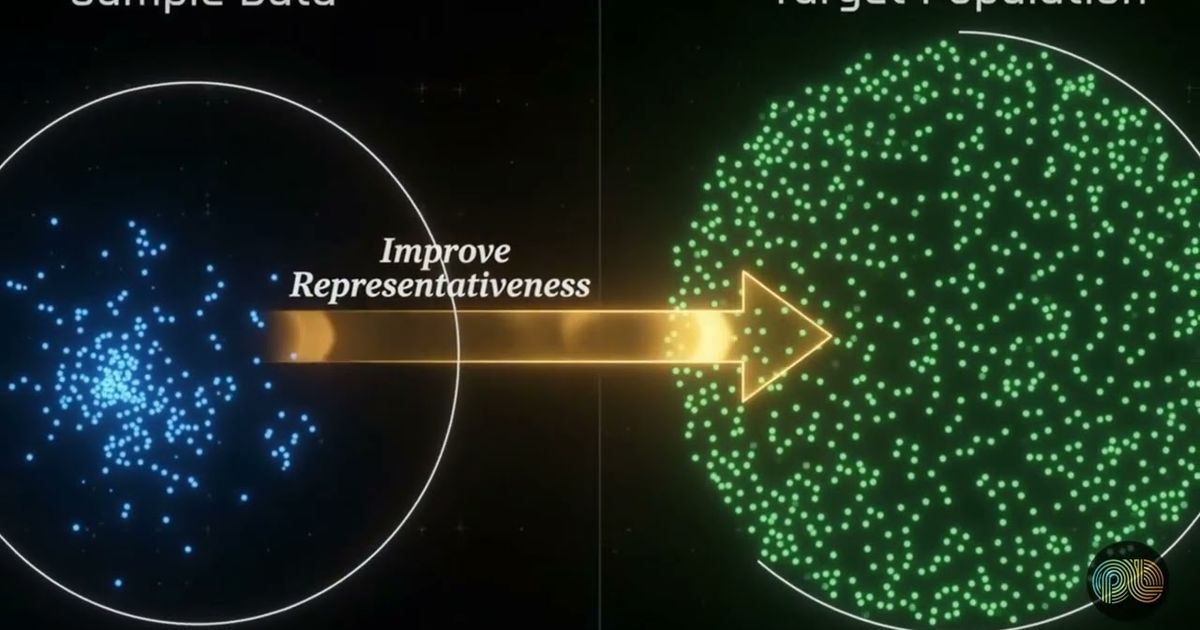
Avoiding sampling bias in market research comes down to catching the usual causes early: participants who are easy to reach, subgroups nobody thought about, and a target population drawn too narrowly. Sampling bias itself means the people you recruit don't accurately reflect the population the study is meant to describe. Any of those causes can steer careful data toward wrong conclusions.
It's one of the quietest ways research goes wrong. The charts come out clean. The results are statistically significant. The summary sounds sure of itself. And all of it describes people who aren't the ones your decision will affect.
What causes sampling bias?
Convenience, mostly. Researchers recruit whoever answers fastest or is easiest to contact, not whoever the question actually calls for.
Email lists, app users and panel regulars end up standing in for everybody. Or the brief rules out people who should have been in, because the population was defined too narrowly. Or participation is uneven: some groups are less likely to respond or finish, so their views are underrepresented even though they were invited.
Each one works quietly. Imagine a survey that hits its target number of responses and still misses an important segment completely. Nothing on the dashboard would warn you. That's one reason response quality matters more than response rate when you're deciding whether to trust a dataset.
What is sampling bias in market research?
A mismatch. The people who took part in the study aren't the people its findings are supposed to speak for.
So the data collection can be flawless and the results still lean, because the group answering was never representative to begin with. The lean can creep in at more than one point. Recruitment may favor whoever is simplest to reach (existing customers, highly engaged users) while quieter segments never get heard. Or the audience gets described so tightly that it leaves out people whose behavior matters to the decision.
How do you build a sampling plan that avoids bias?
Who exactly are you studying? Answer that first, specifically, for the population your research question depends on. Then ask which characteristics (demographics, behaviors, tenure, role, prior experience) could plausibly shape the answers you'll get.
After that, fit the sampling approach to what the study is for. Some questions need broad representation of a whole population. Others should focus, deliberately, on a narrow group with a particular experience, such as recent churners or first-time users.
We'd stress one thing: bias isn't really about how wide the sample is. It's about whether that width fits what you're trying to learn. Write your recruitment criteria down at the start, where everyone can see them, and later you can check whether the plan was actually followed.

How do you check for bias after data collection?
Look at who answered before you look at what they said.
Which groups are overrepresented? Which are missing? Which were invited but less likely to take part? A thin response from one segment is a source of bias in its own right.
Do this check before you draw conclusions, while there's still time to weight the data, recruit a supplemental group or qualify the findings. Perfect representation is rarely possible in practice. What you can do is name the gaps that remain, so your team reads the results with some caution instead of false confidence.

How PulseLake helps
PulseLake holds a study's objectives, methodology and evidence in one persistent study context, so the population a sampling plan is meant to represent stays tied to the original research question through the whole project. Its traditional research mode covers the surveys, panels and assessments where sampling plans get carried out, and synthetic research lets teams pressure-test an instrument against explicit, versioned personas before recruiting real participants. If you want help defining a sound sampling plan, talk to our team.
Frequently asked questions
Is sampling bias the same as having a small sample size?
No. A small sample can still be representative if you choose it carefully, and a big one can be badly biased if it systematically leaves out certain groups. Sample size affects precision; sampling bias affects whether you're looking at the right population at all. Fixing bias therefore means changing who you recruit, and recruiting more people from the same source won't do it.
Can a large sample still produce biased results?
Yes, and often. Thousands of responses from a convenient source, like an email list of current customers, won't make up for the groups that list leaves out. Volume raises your confidence in the estimate's precision, not in the recruitment behind it. A large biased sample can even be riskier than a small one, since its size looks so reliable.
How is sampling bias different from response bias?
Sampling bias is about who gets invited or is eligible to take part; response bias is about how the people who did take part chose to answer. You can have a representative sample and still get response bias if, say, participants give socially desirable answers. Both distort findings, but the fixes differ: recruitment for sampling bias, question design and survey experience for response bias.
Can technology fully eliminate sampling bias?
No single tool removes it, because sampling bias starts in recruitment decisions and population definitions, not in data processing. Technology can make it easier to track who was invited, who responded and which segments are underrepresented, so checks get faster and more consistent. Avoiding sampling bias still comes down to researchers defining the population correctly and judging participation honestly.