Evaluating AI-Generated Research Outputs
AI speeds up research, but outputs still need verification. Learn how to evaluate AI-generated summaries, themes and interpretations for accuracy.

Evaluating AI-generated research outputs means checking whether AI-produced summaries, classifications, themes, comparisons or interpretations accurately represent the original evidence before a team relies on them for a decision. The uncomfortable part is that AI output always looks finished. AI is fast, and fast isn't the same as accurate, so a check against the source is a necessary step.
Say a model summarizes thirty interviews. It comes back tidy and confident, and it reads exactly the same whether the model got it right or quietly bent what people said.
We think that polish is the real risk. Hand a junior researcher's messy draft to someone and they read it slowly, because it looks like it needs reading. A clean AI draft gets skimmed. Skip the check and you may end up building real decisions on outputs that shifted meaning, dropped context or reflected the limits of the data the system was built on.
What counts as an AI-generated research output?
Anything the model gives back from raw research data: summaries, classifications, themes, comparisons, a suggested reading of the results. Useful starting points, all of them, and nothing more until someone checks them against the original evidence.
The stakes differ a lot by type. A misclassified open-ended response costs you one data point. A wrong interpretation that survives into a strategic recommendation can cost a quarter. So match your checking time to what the output will be used for.
How do you check an AI output against the source material?
Put the source next to the output and read. That's most of the method.
Three questions drive the reading:
- Did important context get removed?
- Did the AI's wording quietly shift the original meaning?
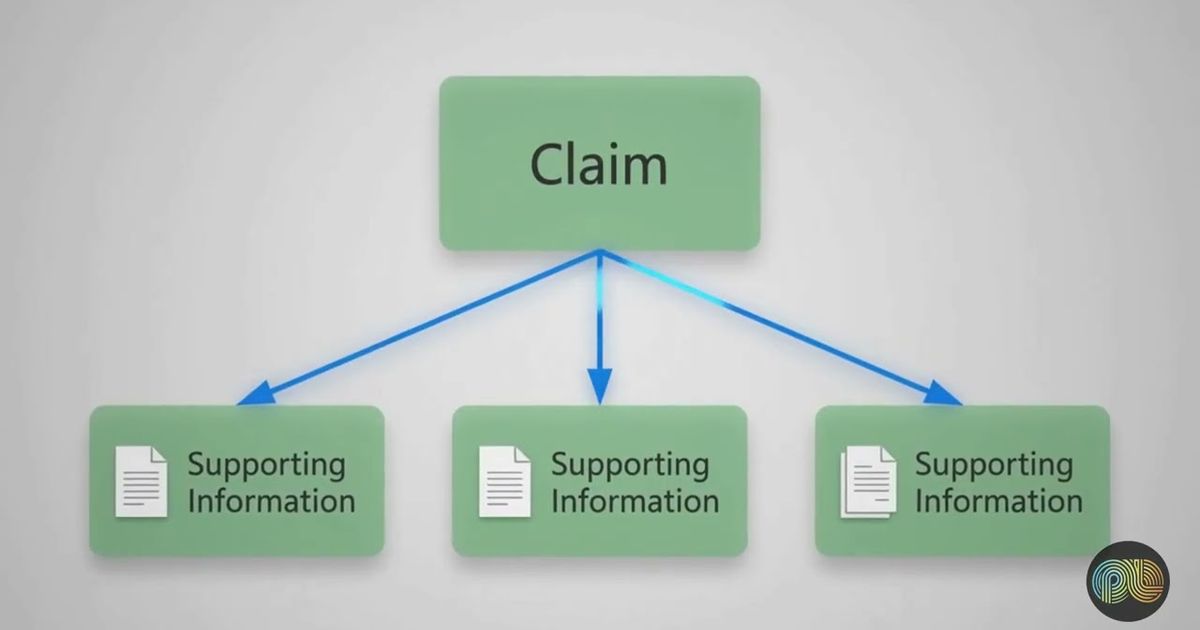
- Is every conclusion supported by the underlying data?
Watch qualifiers in particular, because models love to drop them. "Only if the price is right" turns into plain enthusiasm more often than you'd expect.
Do you have to check every data point? No. Do it for any output that will influence a meaningful decision, and a spot-check of a sample, theme by theme or summary against the raw responses behind it, is usually enough to catch systematic errors. A hypothetical: the model hands you six themes from 200 open-ended comments. Read ten comments per theme and you've read sixty, an afternoon at most. If two of the ten under a theme don't fit, you've learned something important about that theme.

How much scrutiny do AI-generated research outputs need?
It depends on what the output is for, and how it was produced doesn't change that. A draft summary that helps a researcher get oriented before a debrief needs a quick look. An interpretation that will directly shape a major strategic decision deserves the full treatment.
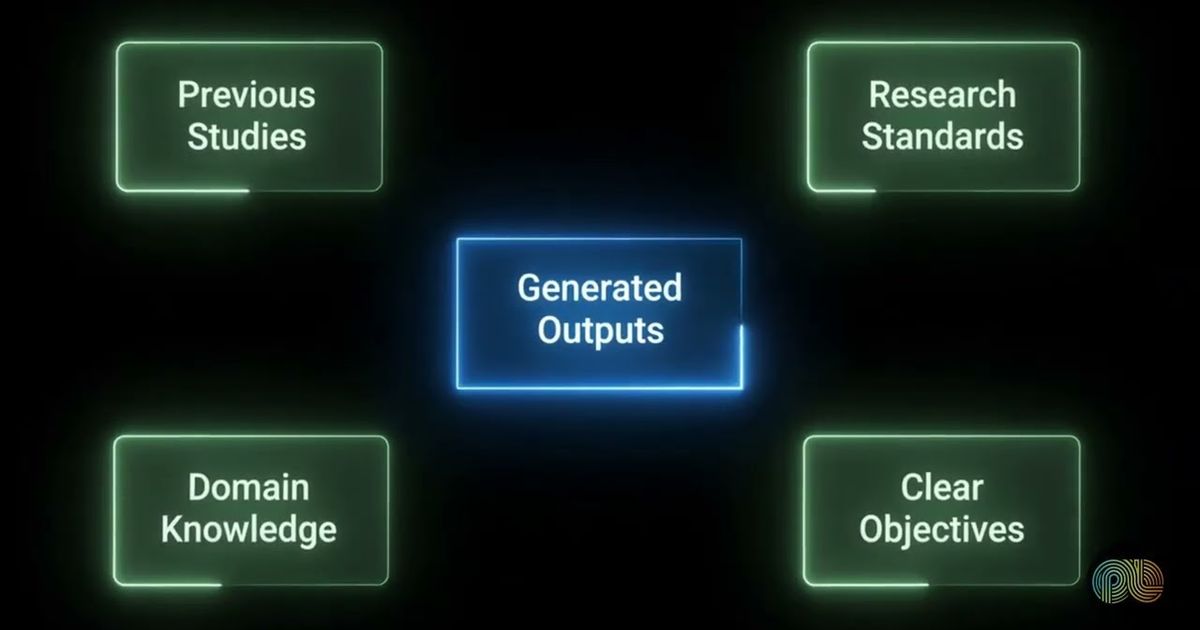
Teams get more consistent when they agree on what "checked" means. A short shared standard does it, with five items: accuracy, completeness, consistency, relevance and alignment with the original research objectives. Is it accurate? Is anything important missing? Does it hold across the whole dataset? Does it still answer the question the study was meant to answer? Every output gets held against the same list before it moves on.
For a wider view of where AI belongs before an output ever reaches this step, see where AI actually fits in the research workflow.

How do you evaluate an AI output for bias?
As its own step, apart from accuracy. It's the one people skip.
AI systems can reflect patterns and limitations in the information used to develop them, so a summary can be right about every individual point and still lopsided. Ask whether certain perspectives were overlooked, underweighted or represented unfairly in a theme, summary or interpretation. Who's missing? If three people out of forty described a serious problem, does it appear anywhere in the summary?
Open-ended and qualitative data is where this bites hardest. Nuance, tone and minority viewpoints are harder to check at a glance than a plain factual claim. Take sarcasm: "Great, another login screen" is not a compliment, yet it can get filed as one.
How PulseLake helps
PulseLake's AI agents support qualitative analysis, deep research and reporting while researchers keep judgment and approval over what those agents produce, so evaluation is part of the workflow from the start. PulseLake's research intelligence layer keeps evidence provenance attached to every finding within a persistent study context, which means teams can trace an AI-generated output straight back to its source material. Our piece on where AI actually fits in the research workflow covers how that division of labor should work. If you'd like help building evaluation checkpoints into an AI-assisted workflow, talk to our team.
Frequently asked questions
What is the fastest way to spot-check an AI-generated summary?
Read a sample of the raw responses behind it, side by side with the summary or theme. Look for context that got dropped and meaning that drifted. You needn't review every data point, since a representative sample usually shows whether you're facing a one-off or a systematic accuracy problem.
Do all AI outputs need the same level of review?
No, and trying to give everything a full manual audit is how teams give up on reviewing altogether. A draft summary used internally to get oriented needs less scrutiny than an interpretation feeding a strategic recommendation. Scale the effort to the stakes of the decision.
Why can AI-generated themes reflect bias even when the underlying data is accurate?
Because AI systems can carry patterns and limitations from the information used to build them. Certain perspectives can end up overlooked, underweighted or represented unfairly even when no individual data point is wrong. That's why we treat bias evaluation as a separate check from verifying factual accuracy.
Who should be responsible for evaluating AI-generated research outputs?
The researcher who owns the study and the decisions that come out of it. Good evaluation depends on knowing the research objectives, the source evidence and how a finding will be used. AI can speed up producing a summary or theme, but verifying it stays with the person accountable for the conclusion.