Benchmark Libraries for Capability Development
Benchmark libraries provide structured reference models, criteria, and maturity examples to help teams assess capabilities and prioritize improvements.

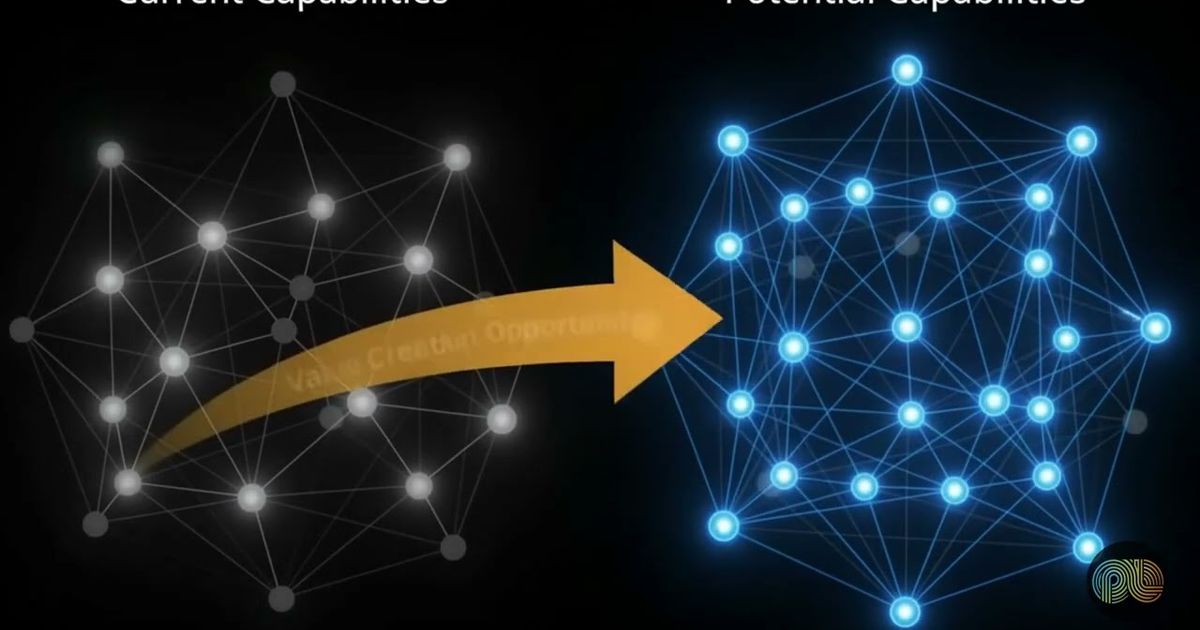
Benchmark libraries are organized collections of benchmark definitions, assessment criteria, maturity examples, best practices and reference models. For capability development they give a team shared reference points: a way to judge where you stand today, see what good performance can look like and choose improvements that are realistic. They don't turn anyone else's practices into a universal template.
Only looking inward has a blind spot. Your own observations will show you your limits. They rarely show how many ways you could grow. A well-kept library supplies that wider view, keeps evaluations consistent and helps assessment findings turn into things people actually do.
What is a benchmark library?
Think of a structured knowledge base. It lets you hold current organizational practice up against established patterns, principles and capability levels, with a shared vocabulary for talking about performance and the next step up.
A folder full of case studies doesn't qualify. What makes it a library is organization: the same reference material, applied the same way, every time. Teams use one for formal assessments, strategic planning, operating-model reviews or building a wider assessment framework.
Nobody gets crowned universal standard here. The library helps decision-makers see what effective performance can involve, what conditions support it and how a capability might develop over time.
What should a benchmark library include?
Definitions, criteria, examples, practices and models, each one helping a reader understand the capability being evaluated and the context behind the reference point.
Six components show up most:
- Benchmark definitions: what each capability means.
- Assessment criteria: how to evaluate it.
- Maturity examples: what different levels of development look like.
- Best practices: approaches linked to good outcomes.
- Reference models: how capabilities, processes and responsibilities relate.
- Contextual conditions: where a practice may or may not apply.
We'd defend that last one hardest. Record the principles behind an example, not only the example from a successful organization. Principles travel. A copied practice often leans on structures, resources, technology or goals that you don't have.

How do you use benchmark libraries for capability development?
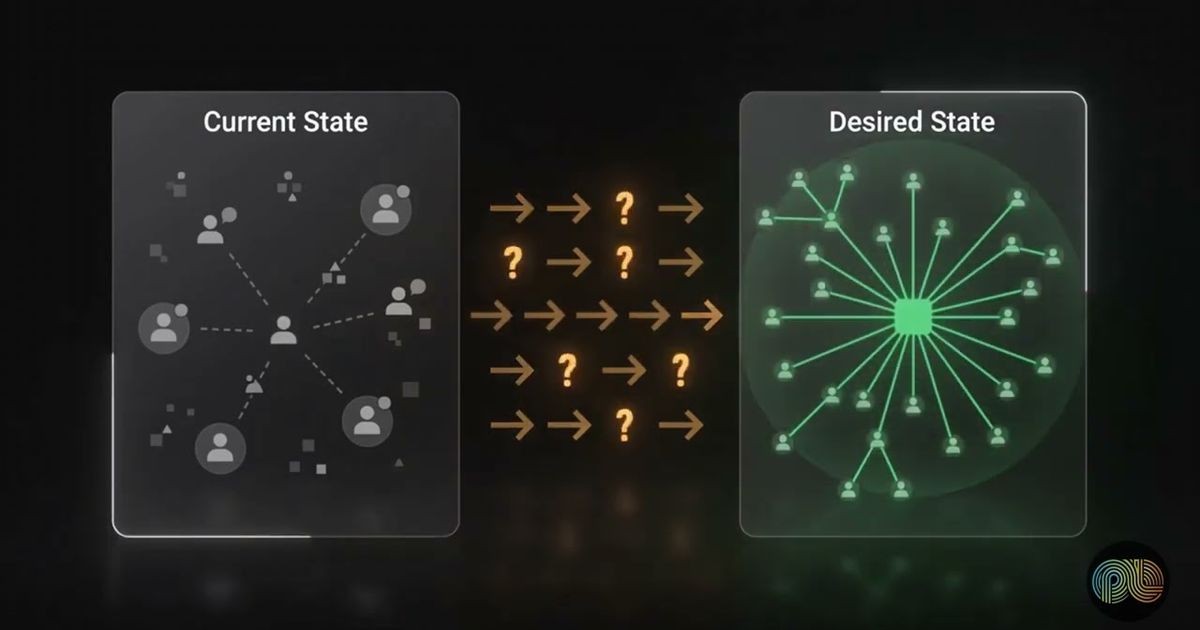
Use the library to work out where you are, look at credible paths forward and pick improvements that suit your situation. The benchmark feeds your judgment. It doesn't stand in for it.
Begin with two things: the capability, and the decision under review. Put current practice next to the relevant criteria and maturity examples. Which gaps change the outcomes you want? Those are the ones to rank, by weighing strategic importance, dependencies, how feasible the fix is and what conditions success needs.
A quick picture. Say an organization is assessing its research intelligence. It could look at how different maturity levels handle evidence management, knowledge reuse, governance and AI-supported workflows. The references might point to several workable development paths, and none of them assumes everybody should adopt the same model. That work gets stronger alongside practices for organizing research into reusable knowledge.
The end product is an improvement strategy that fits your context. Chasing a score for its own sake helps nobody. Benchmark findings pay off when they say what to strengthen, why it matters and what a realistic next state looks like.
How should benchmark libraries be managed over time?
Actively. Somebody has to organize, interpret, review and update the thing. AI can take on part of the information handling and discovery, but a person stays responsible for deciding whether a comparison means anything.
What can AI do? Sort big piles of reference material, find relationships between examples and bring up comparisons that fit a particular question. A large library gets easier to search, and linking related models, criteria and practices costs less effort.
Why keep people on interpretation? Because benchmarks depend on context. A practice that works in one operating environment can be wrong in another, and two things that look alike may differ in goals, governance, resources or constraints.
Then there's staleness. Technologies, organizational practices and research methods all change, and an old reference can nudge a capability decision the wrong way. Owners should go back through definitions, examples, criteria and models on a schedule, so the library matches current understanding and keeps its context.

How PulseLake helps
PulseLake keeps research objectives, methods, evidence and decisions in a persistent study context, backed by a research knowledge graph and cross-study search. Teams can structure benchmark knowledge through ontology, governance and lineage, then package assessments, methods and workflows as reusable intellectual property. To talk about how this could support your capability development process, talk to our team.
Frequently asked questions
Can a small organization benefit from a benchmark library?
Yes, as long as it starts small on purpose. Cover a few strategically important capabilities, not a sprawling repository. Value comes from consistent definitions, relevant criteria and examples with context, not from volume, and even a focused library can reduce subjective assessment and make your priorities easier to explain.
Is a benchmark library the same as an assessment framework?
No, though they work together. The assessment framework says how a capability will be evaluated: dimensions, criteria, rating approach. The benchmark library is wider. It holds many definitions, examples, maturity patterns, practices and reference models, and the framework can draw on it when setting criteria or interpreting results.
Should benchmarks come only from high-performing organizations?
We'd advise against it. Useful benchmark knowledge covers several maturity levels, alternative operating models and examples that show important conditions or limits. Look only at top performers and you can miss how capabilities develop and what they need first. The best references explain why an approach works and when it may not transfer.