Canonical Research Models Explained
Canonical research models give teams a shared structure for questions, evidence, findings, and decisions, improving comparison, reuse, automation, and AI.

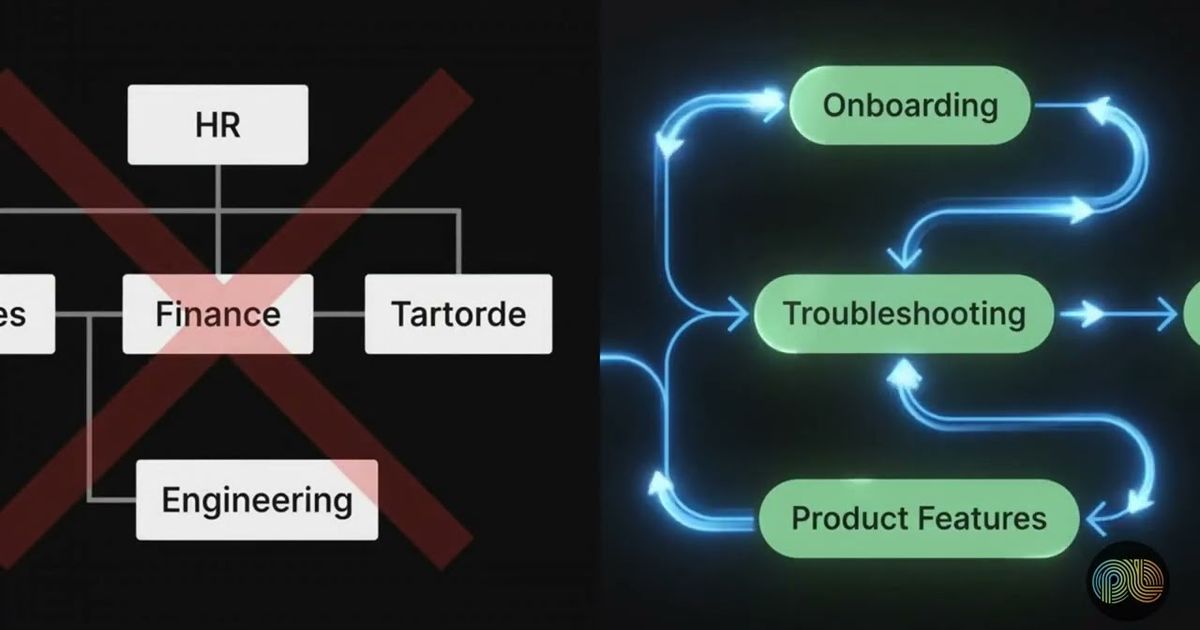
A canonical research model is a standardized representation of the core objects, relationships and definitions used across a research system. Every study gets the same conceptual structure for questions, evidence, observations, themes, findings, recommendations and decisions, while researchers stay free to use their own methods, terminology and project-specific details.
Now imagine there's no model. One team logs "pain points," another logs "friction," a third logs "barriers," and nobody can say whether they found the same thing.
The result: research that's harder to compare, harder to automate and harder to reuse.
What is a canonical research model?
Think of the grammar of organizational knowledge: the stable concepts and relationships your research projects share. It doesn't dictate the exact words a researcher must use. (Searched "what is a canonical model" in a data context? Same idea there: one agreed shape that many sources map onto.)
The usual objects are research questions, which define what a study is trying to understand; evidence and observations from research activities; themes and findings from analysis; and the recommendations and decisions tied back to that evidence. Each keeps the same definition and structure from project to project.
The relationships count just as much. A finding may derive from several observations, support a recommendation and inform a decision.
Studies can still add specialized fields, methods or terminology, and they map those details back to the lasting model. One thing it isn't is a research taxonomy. A taxonomy organizes labels and categories; the canonical model defines the broader objects and connections that hold the whole system together.

Why do canonical models improve AI-assisted research?
Ambiguity is where AI systems go wrong, and a canonical model strips out a lot of it. Similar ideas get common definitions and predictable relationships, which helps retrieval, synthesis and reasoning across studies written in different language or formats.
Picture an AI workflow running over an unstructured pile of reports. Every time, it has to guess whether "friction" and "barrier" mean comparable things. Hand it a canonical structure instead and it can follow explicit mappings and relationships, not just match terminology.
Predictable structure makes automation more dependable as well. Retrieval can target defined evidence types, synthesis can connect observations to findings, and reasoning can follow the lineage from a research question all the way to recommendations and decisions.
None of that replaces researcher judgment. Someone still has to inspect provenance, weigh evidence quality and approve interpretations, especially when AI pulls from several projects at once. Preparing AI-ready research data takes consistent structure and proper governance, both.
How do canonical models keep studies compatible?
Every study's outputs map to the same concepts. Teams keep their local language; equivalent ideas get a shared structural meaning.
Back to pain points, friction and barriers. A canonical model can classify all three as related expressions of one underlying research concept without wiping out the distinctions that matter inside each study. The customer research team still says "pain points." The product team still says "friction." Both land in the same place.
Comparing or combining research then takes less manual interpretation. Reuse improves too, because people can find relevant evidence by meaning and structure and not only by exact keyword matches.
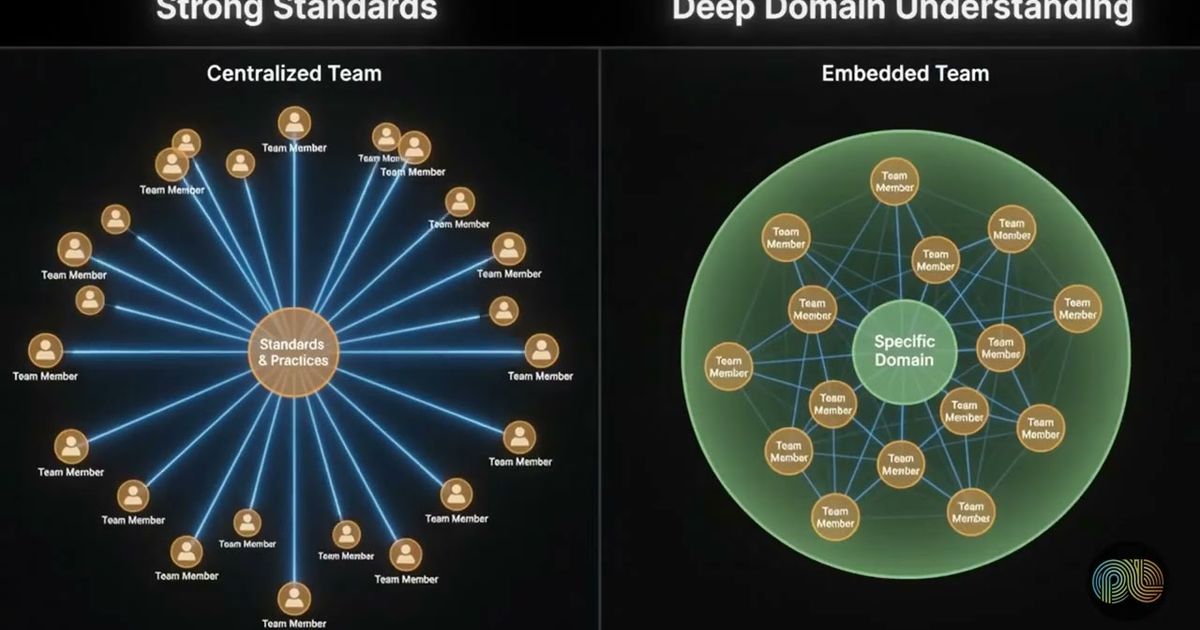
We'd call it consistency without uniformity. Teams still investigate different problems and still choose qualitative, quantitative or mixed methods; their outputs just slot into a shared organizational framework afterward.
What mistakes should teams avoid?
Two opposite ones: being too rigid, and being too loose. Rigidity forces projects into categories that don't suit them. Looseness brings back the very inconsistency the model was meant to fix.
Four slips are worth naming:
- Standardizing terminology without defining the underlying concepts and relationships.
- Treating every new project field as a permanent canonical object.
- Changing core definitions without keeping the mappings to earlier research.
- Assuming shared structure removes the need for interpretation and governance.
Our view is that the third does the most damage, because it quietly breaks years of earlier work.
The model isn't there to tell researchers how to think. It's there to give varied research outputs a stable footing, so they stay understandable, comparable and reusable.
How should a canonical research model evolve?
Slowly, and on purpose. A good model holds steady while allowing controlled change, so new concepts can come in without breaking existing knowledge or shifting the meaning of what's already there.
Start by separating lasting research concepts from project-specific details. Questions, evidence, findings and decisions tend to stay put across many studies, while a single project might need its own attributes, categories or measures (and that's fine).
When a genuinely new concept does appear, define it, spell out its relationships and map it to existing knowledge where it fits. Leave previous mappings intact so older studies stay readable and compatible.
Do that and the model grows without constant redesign. Knowledge keeps piling up in one coherent system, not splitting into collections that can't talk to each other.

How PulseLake helps
PulseLake keeps objectives, methodology, evidence, findings and decisions in a persistent study context backed by ontology, governance and lineage. Its research knowledge graph and cross-study search let teams ask questions across accumulated evidence without losing provenance. If you'd like to see how this could support a canonical research model, talk to our team.
Frequently asked questions
Is a canonical research model the same as a research taxonomy?
Not quite. A taxonomy, sometimes called a canonical taxonomy when it's the agreed master list, mainly sorts concepts into categories and sets preferred labels or hierarchies. A canonical research model is broader: it defines research objects, their attributes and how they connect, such as the link between an observation, a finding, a recommendation and a decision. The taxonomy can be one piece of that model.
Can qualitative and quantitative studies share one canonical model?
Yes. The model standardizes shared research concepts and doesn't force every study into one method or data format. Interviews, surveys, assessments and mixed-method studies can all map questions, evidence, findings and decisions to common structures, while keeping method-specific details such as transcripts, variables, scales or sample definitions.
Who should approve changes to a canonical research model?
Shared ownership works best, among the people responsible for research practice, knowledge management, data architecture and governance. Changes need enough oversight to protect compatibility, but researchers should still be able to propose additions they need. Every change wants a clear definition, documented relationships and a plan for keeping the meaning of existing research intact.