Research Taxonomies Explained
Research taxonomies create a shared structure for classifying studies and insights, making findings easier to discover, compare, reuse, and understand.

Research taxonomies are structured systems for grouping studies, insights, users, problems and themes by shared characteristics and relationships. A taxonomy gives information consistent categories and definitions. That creates a common language, so people can find relevant evidence, compare findings, connect related work and see what the organization already knows.
Research nobody can find might as well not exist. Findings get scattered, labeled three different ways and buried in slide decks.
A practical taxonomy fixes a lot of that. Knowledge management improves, duplicated work drops, and collaboration, analysis and decisions all get a firmer base.
Why do research teams need research taxonomies?
Imagine someone commissioning a study that already exists, because the earlier one was filed under another word. It happens when categories aren't shared. People search for the same concept in different terms, miss relevant work, or repeat it.
Consistent labels on studies and insights change that. Related evidence turns up faster, and patterns across projects start to show. Consistent classification turns isolated reports and findings into a body of knowledge you can navigate, whether the work is product research, UX studies or market research.
Collaboration gets easier too. Researchers, product teams and leaders read information more reliably when key terms mean the same thing to everyone. Analysis and decisions stand on firmer ground, because people can see how findings connect instead of treating each report as a standalone document.
This structure sits at the heart of organizing research into reusable knowledge. It also helps you build a research repository that people actually use, since retrieval only works when the categories match how people look for answers.
What is a research taxonomy?
An organized classification system for research information. It defines the categories, terms and relationships your teams use to describe their work and find their way around it, the same way every time.
Depending on the organization, it might classify studies (by method, audience, market, product or business question), insights (by topic, theme, behavior, need or opportunity), users (by role, segment or context) and problems (by journey stage, product area or type of friction). It can also cover themes that recur across several projects.
A folder structure it isn't. A folder usually puts an item in one place, while taxonomy labels can tie one study to several concepts at once. A study on onboarding friction can be classified by audience, journey stage, product area, method and research theme together.
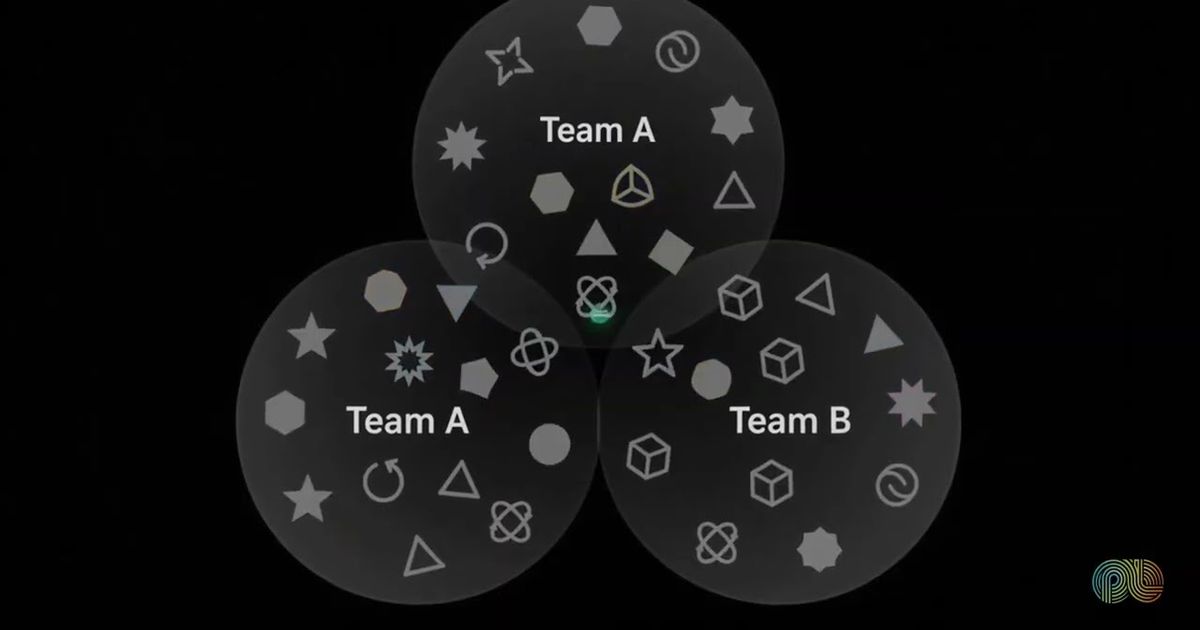
Definitions do much of the work. Say one team uses "customer" to mean a buyer and another means any end user. Two searches that look identical will then pull up mismatched evidence. Defined terms are what turn labels into a shared research language.

What mistakes should you avoid when managing a taxonomy?
Three do most of the damage: designing categories around internal structures, leaving terms undefined, and treating the taxonomy as permanent. Any one of them makes the system less useful as research practices and organizational knowledge change.
Copying the org chart is the classic. Departments and reporting lines change, and they rarely match how people search for evidence. Ambiguous labels come next: similar words mean different things across teams when nobody has made definitions and boundaries explicit.
Then there's excessive detail. A taxonomy that's hard to apply consistently ends up with fragmented or incomplete classification. Uncontrolled synonyms split related evidence across separate search paths. A frozen structure misses what new findings reveal, such as emerging themes or categories that should be combined, separated or renamed. And label changes without governance break the connections to research classified earlier, so updates should keep those intact and stay understandable to users.
Aim for stable enough to be consistent, flexible enough to absorb what you learn. We'd stop chasing a perfect system that never changes. Good research taxonomies just make research easier to find and understand.
How do you create a useful research taxonomy?
Start with who'll use it. What do they need to find, and how do they naturally search? Follow real research and decision needs; the org chart makes a poor template.
Review real search needs first: collect the questions stakeholders ask, the words they use and the filters that would help them find evidence. Pick a manageable set of core categories for studies, insights, audiences, problems, methods, themes or other recurring concepts. Write a clear definition for each term (what it includes, what it excludes, how it differs from its neighbors). Then test it on existing and new research, and revise any label that confuses people or doesn't help retrieval.
Don't try to classify every possible detail. More categories mean more tagging effort and harder navigation. Begin with enough structure to improve discovery, and add distinctions only when real research needs call for them.
Settle ownership early. Who can propose terms? Who approves changes, resolves overlap and retires categories that stopped helping? Answer that, and the taxonomy stays consistent while it still gets to grow.

How PulseLake helps
PulseLake keeps objectives, methodology, evidence and decisions in a persistent study context, and its research knowledge graph and cross-study search help teams connect information across projects. Ontology, governance and lineage give you foundations for organizing knowledge consistently, and natural-language questions keep their evidence provenance. To discuss how this could support your research system, talk to our team.
Frequently asked questions
What is the difference between a research taxonomy and a research repository?
A repository stores studies, evidence, reports and related materials. A taxonomy supplies the categories and shared terms used to organize and retrieve them. Think of the repository as where knowledge lives and the taxonomy as how people navigate it, connect related findings and search consistently across projects.
How often should a research taxonomy be updated?
Review it when search behavior, research priorities, audiences, products or recurring themes change. Let demonstrated needs drive updates, not a fixed calendar. Keep definitions and a change history, so revised categories don't cut older evidence off from current research.
Can one study belong to multiple taxonomy categories?
Usually it should. A single study often touches several audiences, methods, product areas, journey stages, problems and themes. Applying every relevant category makes the research findable from different starting points, provided the labels are clearly defined and researchers apply them consistently.