Finding Themes in Thousands of Responses
Finding themes in thousands of survey responses requires structured coding, grouping and validation, not just reading for repeated words or phrases.

Finding themes in thousands of responses means boiling a huge pile of open-ended feedback, comments or interview transcripts down to a manageable set of recurring ideas researchers can act on. It combines structured coding, computational help with organizing the data, and human interpretation to confirm which patterns genuinely mean something.
Got a few dozen comments? Read them. You'll see the patterns, and that's fine.
Got several thousand? Reading breaks down, and without a structured process the signals that matter most stay buried in the volume.
Why is finding themes hard at large scale?
Nobody can read it all. The useful insight is sitting in there somewhere, but past a certain volume you won't reach it by reading, and patterns don't announce themselves.
We'd call this a scale problem more than a time problem. A researcher with a hundred responses can keep the patterns in their head. A researcher with ten thousand needs a process that doesn't depend on memory at all.
How do you prepare large response collections for analysis?
Clean the data first. Strip out whatever's irrelevant and organize the text so every response gets analyzed the same way. Skip this and the results turn noisy later, however good your method is.
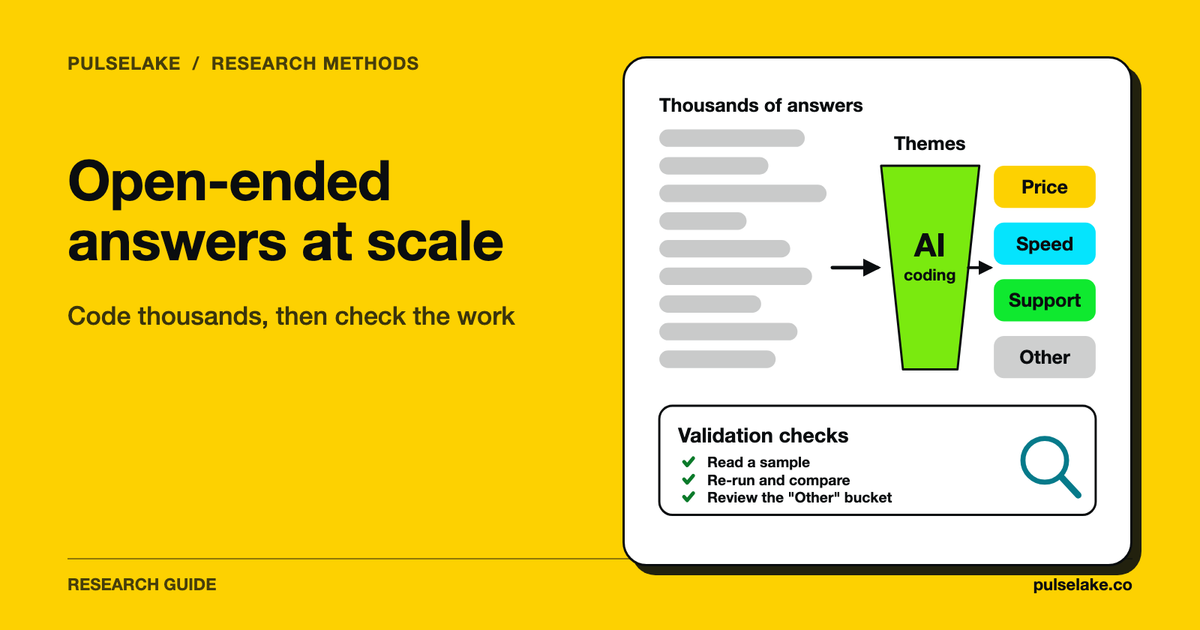
Then comes coding, the core analytical step. Researchers tag each important idea, behavior or experience in a response with a label, and then group labels that belong together. Those groups are what finally show you the broader themes across the whole set.

What role does computational assistance play?
A big one in sorting, a small one in deciding. Modern research workflows can lean on computational assistance to organize large datasets and flag possible patterns, but interpretation stays with people throughout. Automated systems are good at surfacing candidates. Judging which candidates matter isn't something they do well.
That's where AI-assisted theme extraction comes in. It takes over the mechanical work of organizing text, so researchers can spend their hours on the interpretive work that decides whether a pattern is meaningful.

How do you know a theme is actually important?
Not by counting. A topic people mention often isn't always the most important issue in the data. Good theme identification looks past repeated words to context, emotional weight and the way different ideas connect.
Here's a hypothetical survey. Lots of people write "the app is slow." A few write "I lost a client's data." Count words and the first wins. Read for consequence and the second probably matters more.
To trust a theme, check it:
- Does it hold up across different participant groups?
- Do the original responses behind it say what its label says?
- Does your conclusion represent what was actually collected?
Topic clustering and sentiment analysis add complementary ways to test whether a pattern from coding matches how the underlying text reads.
How PulseLake helps
PulseLake pairs AI agents for qualitative analysis with a persistent study context, so themes drawn from thousands of responses stay connected to the original evidence and to the objectives the study was built to answer. Cross-study search and a research knowledge graph help teams check whether a theme from one project also appears in related studies, which adds validation beyond a single pass through the text. Talk to our team to see how PulseLake scales qualitative analysis end to end.
Frequently asked questions
How many responses count as "large scale" for theme analysis?
There's no fixed number. When a team can't read every response and still hold the patterns in mind, manual review stops being reliable. That typically starts somewhere from a few hundred open-ended responses upward, depending on how long the responses are and how much time the team has.
What is the difference between coding and theming in qualitative analysis?
Coding is first: researchers label the specific ideas, behaviors or experiences in individual responses. Theming is second, when related codes get grouped into broader patterns that represent a common experience across many responses.
Can automated tools fully replace manual review when analyzing thousands of responses?
No. Automated tools are well suited to organizing big volumes of text and surfacing candidate patterns. Confirming that a pattern is meaningful, not merely frequent, still takes human interpretation. A reliable process for finding themes in thousands of responses pairs computational assistance with researcher validation before anything gets reported.
How do researchers validate that a theme is reliable across thousands of responses?
Usually they check that the theme shows up consistently across different participant groups or subsets of the data, then spot-check original responses to make sure it reflects what people actually said. A theme that appears in just one segment, or falls apart on a closer read, needs more investigation before it goes in as a finding.