Knowledge Retrieval Precision Explained
Knowledge retrieval precision helps research systems return relevant evidence, reduce noise, and preserve context, diversity, completeness, and traceability.

Knowledge retrieval precision is the degree to which retrieved information directly answers a specific question. A high-precision system prioritizes relevant evidence and excludes unrelated material, reducing the work required to separate useful knowledge from noise. Effective precision also preserves enough context, diversity, and traceability to support sound research decisions.
This matters because broad but poorly targeted results can slow researchers, confuse AI systems, and weaken confidence in the evidence used for analysis. The two-minute video above walks through the core ideas.
What is knowledge retrieval precision?
Knowledge retrieval precision measures how much of the information returned by a system is genuinely relevant to the question asked. In simple terms, it asks: Of everything retrieved, how much actually belongs in the result set?
High precision means that most results directly address the research question. Low precision means that useful evidence appears alongside loosely related documents, duplicated findings, or material connected only through broad keywords.
Consider a search for evidence about customer trust during identity verification. A low-precision system might return anything mentioning trust, security, onboarding, authentication, or account access. A high-precision system would prioritize findings that directly connect trust to the identity verification experience while retaining supporting context needed to interpret those findings.
Precision is therefore not the same as retrieving fewer documents. It is about selecting the right evidence for the intended analytical task.
How does low retrieval precision affect research quality?
Low retrieval precision increases the effort and uncertainty involved in turning stored knowledge into an answer. Researchers or AI systems must first filter unrelated material before meaningful analysis can begin.
This creates several practical problems:
- Review time increases because every result must be checked for relevance.
- Important evidence becomes harder to recognize when buried among weak matches.
- AI-generated synthesis may blend directly relevant findings with incidental references.
- Researchers may lose confidence that a result set represents the actual question.
Poor precision can also make a repository appear more comprehensive than it is. Hundreds of matches may create an impression of coverage even when only a small portion supports the decision at hand. Organizing evidence through cross-study knowledge linking helps systems distinguish meaningful relationships from superficial keyword overlap.
How can knowledge retrieval precision be improved?
Improving precision requires more than adjusting a search algorithm. The underlying research knowledge must provide clear signals about what each piece of evidence means, where it came from, and how it relates to other information.
Four foundations are especially useful:
- Structured metadata: Consistent fields for study, audience, market, method, topic, date, and evidence type help narrow results to the intended context.
- Semantic relationships: Explicit links among questions, concepts, findings, decisions, and evidence let systems retrieve by meaning rather than exact wording alone.
- Research ontologies: Shared definitions and relationships reduce ambiguity across teams, projects, and terminology. A clear research taxonomy provides a practical starting point for organizing these concepts.
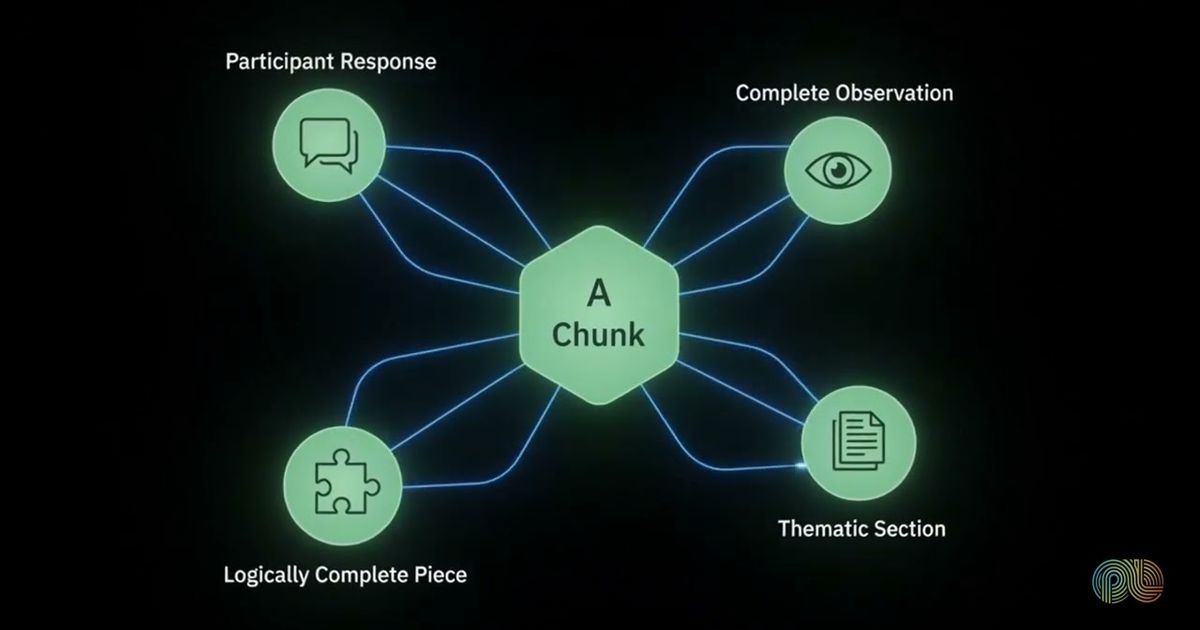
- Clearly defined knowledge objects: Findings, quotes, themes, metrics, hypotheses, and recommendations should be represented as distinct objects rather than undifferentiated files.
Well-organized information gives both people and intelligent systems stronger signals for deciding what belongs in a result set and what should remain excluded. It also makes retrieval behavior easier to inspect and improve.

How should precision be balanced with completeness?
Precision should be balanced with completeness because a narrowly relevant result set can still omit significant evidence. Returning only a handful of strong matches may hide alternative perspectives, edge cases, or contradictory findings.
A robust retrieval process should therefore support both focused answers and deliberate checks for missing evidence. Researchers can begin with the most directly relevant results, then broaden the search across related populations, studies, time periods, methods, or concepts. Contradictory findings should remain visible rather than being filtered out simply because they complicate the emerging answer.
Traceability is equally important. Each retrieved claim should retain a path to its source, study context, methodology, and supporting evidence. This allows researchers to judge whether a result is directly applicable, merely contextual, or potentially in conflict with other knowledge.
The objective is not maximum precision at any cost. It is to deliver evidence that directly supports informed reasoning while maintaining confidence that important knowledge has not been unintentionally overlooked.

Key takeaways
- Knowledge retrieval precision describes how consistently a system returns information that directly answers a specific question.
- More results do not necessarily produce better research when relevant evidence is mixed with unrelated material.
- Metadata, semantic relationships, ontologies, and defined knowledge objects improve retrieval signals.
- Precision must be balanced with completeness, diversity, contradiction awareness, and traceability.
- The best result set supports focused reasoning without concealing significant evidence.
How PulseLake helps
PulseLake maintains persistent study context and a research knowledge graph that support cross-study search and natural-language questions with evidence provenance. Its ontology, governance, and lineage foundations help research teams organize knowledge so retrieved evidence can remain connected to its original context. To discuss how this approach could support your research system, talk to our team.
Frequently asked questions
Is higher knowledge retrieval precision always better?
Higher precision is useful when researchers need a focused answer, but it should not come at the expense of significant evidence. An overly narrow system may exclude contradictory findings, minority perspectives, or relevant studies using different terminology. Good retrieval combines precise initial results with a controlled way to examine broader and potentially conflicting evidence.
How should a research team define whether a result is relevant?
Relevance should be defined against the specific research question, intended population, decision context, methodology, and required evidence type. A document can mention the correct topic without answering the question. Clear inclusion and exclusion criteria help researchers and retrieval systems distinguish direct evidence from background context or superficial keyword matches.
Can AI improve retrieval precision in a research repository?
AI can improve retrieval precision by interpreting semantic meaning, relationships, and study context rather than relying only on exact keywords. Its performance still depends on well-structured source material, clear knowledge objects, consistent metadata, and appropriate governance. Researchers should retain oversight, verify source relevance, and review whether important evidence has been excluded.