Scaling Research Without Sacrificing Quality
Growing research volume doesn't have to mean weaker insight. Learn how repeatable processes and shared standards keep scaled research reliable.

Scaling research means handling more studies, more data and more stakeholders without lowering the quality of the insights that come out. Doing more work faster won't get you there. It takes repeatable processes and shared standards, so planning, recruitment, analysis and reporting stay consistent as volume grows. Automation and AI can support that growth, but only alongside deliberate quality checks and human evaluation.
Would you rather have fewer studies done well, or more studies on shakier evidence? The second is the worse place to be.
Fast research that produces unreliable conclusions creates its own work: decisions get made on weak evidence, then have to be revisited.
What does it mean to scale a research function?
Raising the volume and reach of research activity (more studies, more stakeholders served, more data processed) while the reliability of what comes out holds steady. Running more studies in the same ad hoc way doesn't count.
Volume with no repeatable system breeds inconsistency. One study follows rigorous standards, another cuts corners under deadline pressure, and soon stakeholders can't trust results equally across the organization. They start asking who ran a study before they'll believe it.
Scale well and the process carries the quality. Individual effort alone can't.
Why do reusable frameworks matter for scaling?
Because researchers can apply proven approaches to new studies and skip redesigning the methodology each time. That saves effort and protects consistency in one move. Structured, comparable information also lets teams compare studies and spot patterns across a growing body of work.
The benefit compounds, which is one of the clearest payoffs of scaling well: each new study makes the next one easier and better informed, and the organization stops relearning the same lessons. For related ideas on connecting findings across a growing research library, see identifying hidden patterns across research projects.
What role do automation and AI play in scaling?
They take the repetitive load. Automation and AI can handle repetitive activities, organize information and support workflows at a volume that would be hard to sustain by hand, and they help most with the mechanical parts: scheduling, data organization, drafting and pattern identification across large data sets.
Research automation goes wrong in one specific place. Efficiency gains should never cost you important quality checks or human evaluation. Automate data collection and drop the review that catches poor-quality responses, and you haven't saved anything; you've traded speed for risk. For more on catching that risk, see detecting low quality survey responses.

How do shared standards protect quality at scale?
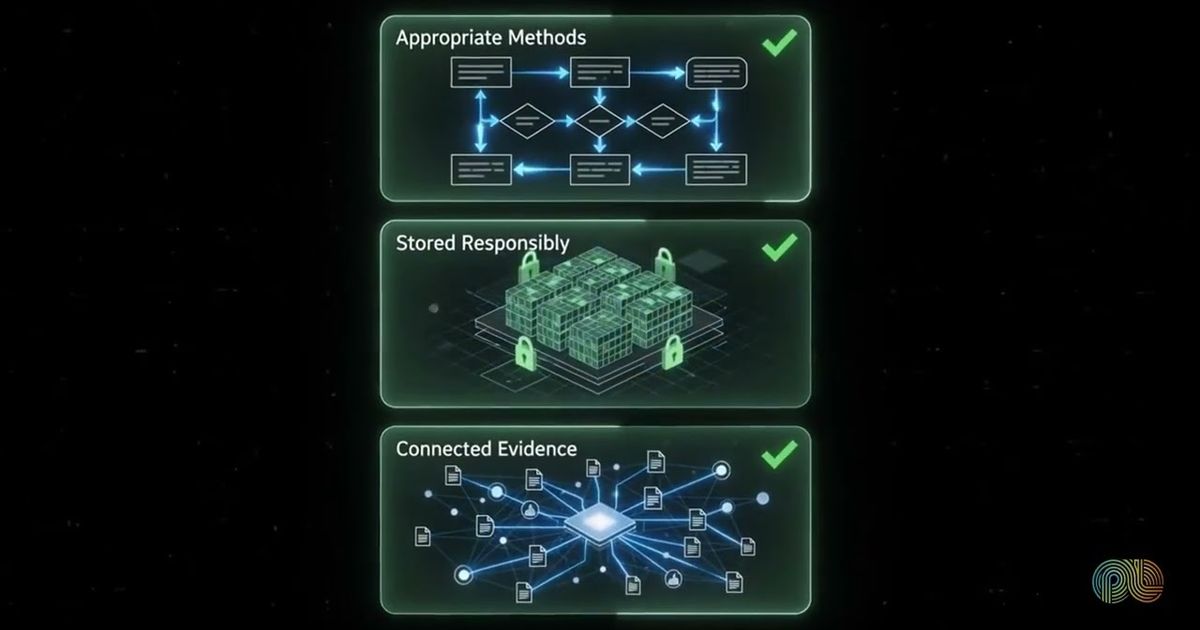
Whichever team or researcher runs a study, it gets the same baseline for defining objectives, collecting evidence, documenting findings and reviewing conclusions. Without one, quality rests entirely on individual habits, and habits don't scale reliably across a growing organization.
Good standards usually cover four things:
- Objective-setting, so each study starts with a clearly defined question.
- Documentation that lets findings be compared and reused across studies.
- Review steps before conclusions reach stakeholders.
- Reusable frameworks, so researchers build on prior work and don't start over.
If we had to pick one, it'd be the review step. It's the first thing to go under deadline pressure, and the one you miss most.

How PulseLake helps
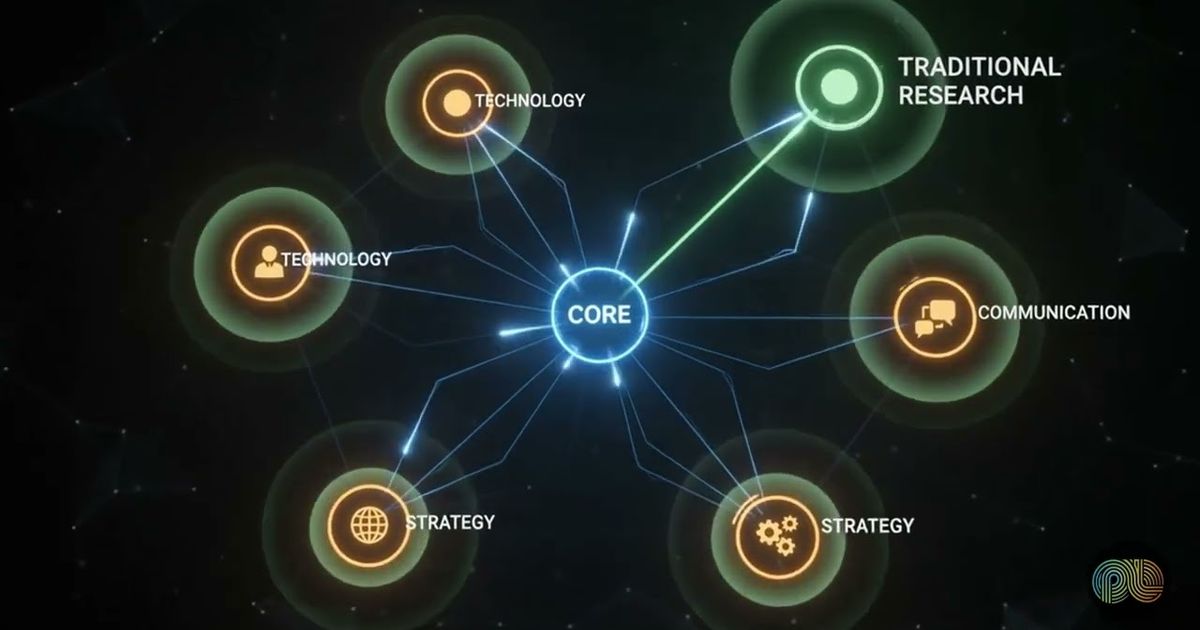
PulseLake supports scaling through workflow automation that runs approvals, QA, recurring studies, reporting and notifications as repeatable flows, and through a marketplace for packaging studies, methods and workflows into reusable, team-wide solutions. Because every study shares one persistent study context, standards and prior work carry forward automatically instead of being rebuilt each time. To talk about scaling a research program, talk to our team.
Frequently asked questions
Does scaling research always require more headcount?
Not necessarily. Repeatable processes, reusable frameworks and automation of repetitive tasks can raise the volume a given team handles without a matching rise in headcount. You'll often still need more people once volume grows a lot, but process and tooling improvements usually stretch a team's capacity before headcount becomes the limit.
What is the biggest risk when scaling research quickly?
Speed replacing careful reasoning, so you end up with research that looks complete but rests on weak evidence. Fast, unreliable research is often worse than doing fewer studies well, since decisions get made on flawed conclusions that later need correcting. Keep quality checks and human evaluation alongside any speed gains and you're protected.
How do reusable frameworks actually save time?
Researchers start from a proven methodology, question set or analysis approach and don't design each study from scratch. That cuts planning effort for new studies and lowers the risk of uneven quality between them, because teams build on validated prior work.
Can research quality be measured the same way as research volume?
Not really, since they need different kinds of tracking. Volume can be counted directly, like studies completed. Quality depends on whether objectives were clearly defined, evidence was properly documented and conclusions were reviewed before being shared. Tracking both gives a fuller picture of a scaling research function than volume alone.