Context Preservation in Research: Keeping Evidence Useful
Context preservation in research keeps findings tied to methods, populations, evidence, assumptions, and limits so teams and AI can reuse them accurately.

Context preservation in research means keeping each finding attached to the information someone needs to read it correctly once the original project is over. That covers the research question, methodology, participant population, evidence, assumptions, limitations and relevant conditions, so later users can verify, compare and reuse the finding without changing what it means.
Findings rarely go bad because they turn out to be wrong. They fade. Nobody remembers when the result applied, who it described or why the first team landed on that conclusion.
What is context preservation in research?
Consider the sentence "customers preferred the simplified interface." Inside its own study it may be perfectly true. Pulled out, it's silent on which customers took part, which interface version they saw, how preference was measured and what business question the study was chasing.
Context preservation keeps the links that give evidence its meaning. A conclusion isn't filed as a lone statement; it stays tied to the decisions, methods, sources and boundaries that produced it.
Keep that context and the same sentence becomes something a future team can use responsibly. They can check it against its source, set it beside later work, and apply it to a new decision without mistaking it for a universal rule.
Wondering what "contextual evidence" means in practice? That. Evidence that arrives with its circumstances attached.
What context should stay attached to a finding?
Anything that could change how someone reads it. Usually that boils down to what was asked, how the work was done, whose experience it represents and where the conclusion stops holding.
Carry these along:
- The research question and the business objective.
- Methodology, instrument and research environment.
- The participant population, and the characteristics that matter.
- Observations, responses, data or analysis behind the finding.
- Assumptions made while interpreting, plus limitations, uncertainties and anything affecting transferability.
Add the product, service, concept or version that was evaluated. Consistent metadata and research taxonomies make all of this easy to record in a reusable form.
But don't document for documentation's sake. Keep the details that decide what the evidence can and can't support.

How can teams preserve context without storing everything?
Capture what materially changes interpretation and skip the rest. Define a small set of required relationships, then keep them alive for the whole life of the research asset.
Start by linking every finding to its research question, supporting evidence, methodology, participant population, assumptions and limitations. Situational details, like product version or research environment, get added whenever changing them could change the conclusion.
Next, make the context travel. Evidence moves into summaries, repositories, dashboards, slide decks and AI-generated answers, and its context has to move with it. Copy a statement and leave its scope and source behind? You've kept the words and lost the meaning.
Last, review the context every time research gets reused. Conditions may have moved on since the original project, so whoever reuses a finding should confirm the population, environment and decision are still comparable.
How does context prevent overgeneralization?
It marks where a finding applies and where you'd need more validation, so nobody can stretch it past the population, conditions or decision it was collected for.
Back to the simplified interface. Without context, another team might decide that every customer segment likes minimal interfaces, across every product. With context they'd see one participant group, one product version, one research setting and one specific business objective.
None of that weakens the finding. It states its scope. The later team can then ask the useful question: are conditions close enough to reuse this, or different enough to justify new customer research?
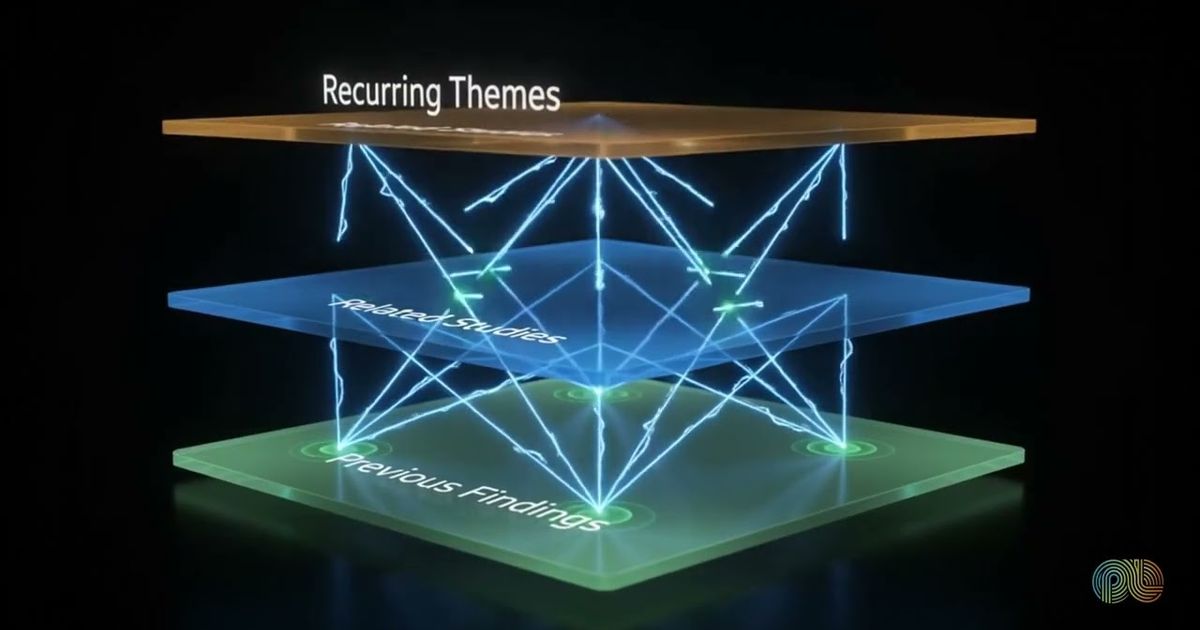
This is the core idea behind building an evidence graph, where findings stay connected to the questions, sources, decisions and constraints that give them meaning.

Why does context matter in AI-native research?
AI systems summarize and synthesize across many sources, and subtle differences vanish unless the boundaries are structured. Related findings get blended into one overly broad story.
Say two studies disagree. Maybe they looked at different customer groups, product versions, markets or usage conditions. To explain the gap, an AI system has to know that. If it doesn't, it averages the two or quietly picks one finding, no caveat attached. We think that's one of the quieter risks in AI market research, and it's a context problem more than a model problem.
Structured context lets an AI-native research system do five things:
- Keep findings separate when their scope differs.
- Flag conflicts without assuming one source is wrong.
- Explain why studies reached different conclusions.
- Trace a summary back to its evidence and methodology.
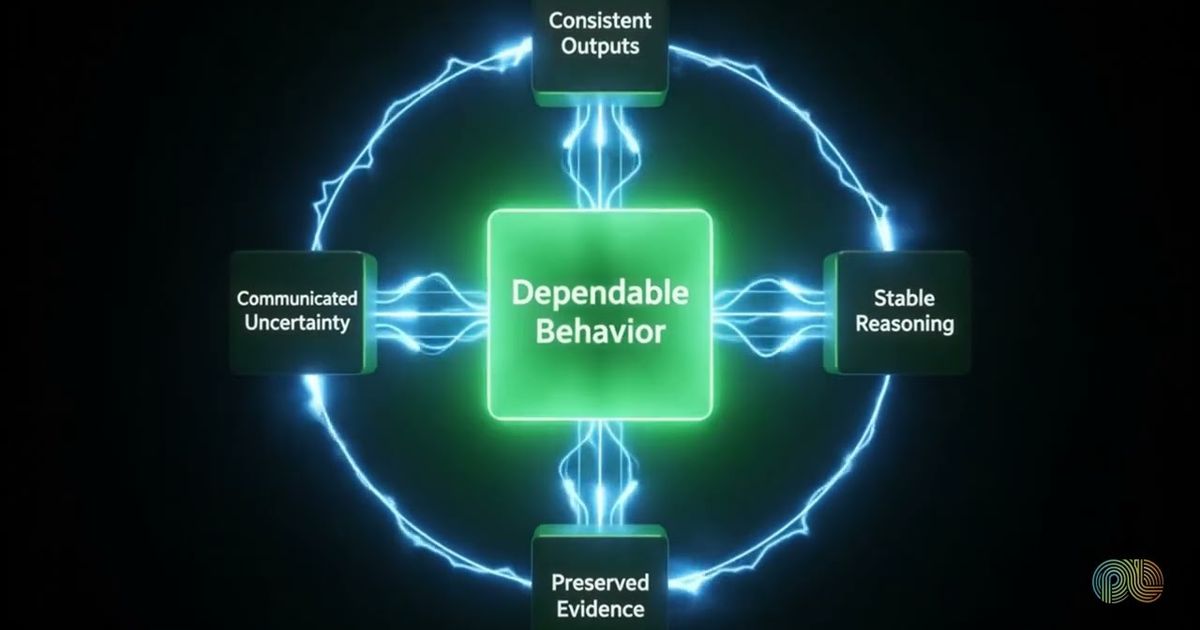
- Pass assumptions and limitations into whatever it produces.
Synthesis gets faster with AI. Preserved context is how a researcher confirms the synthesis still respects the original evidence.
How PulseLake helps
PulseLake keeps objectives, methodology, evidence and decisions in a persistent study context backed by ontology, governance and lineage. Its research knowledge graph, cross-study search and evidence provenance help researchers trace findings, compare studies and ask natural-language questions without separating answers from their sources. To see how this could support trustworthy research reuse, talk to our team.
Frequently asked questions
Can a research finding remain accurate but become misleading over time?
Yes. It can stay accurate for the original participants and conditions and still mislead once someone reuses it as if it applied everywhere. A shift in the market, product, population or business objective can change its relevance. Check the original context before you apply it to a new decision.
Should raw data and research context always be stored together?
Not necessarily in the same file or system, but they must stay reliably connected. A finding should offer a traceable path to its evidence, methodology, population, assumptions and limitations, subject to appropriate access and governance controls. The connection matters; where things physically live doesn't.
How does preserved context help when two studies disagree?
It lets researchers compare the conditions behind each conclusion. Participant populations, methods, product versions, research environments or questions may explain the gap. Instead of forcing both studies into one story, teams can work out whether the evidence truly conflicts or simply applies to different situations.
Who is responsible for maintaining research context?
Research teams define the context required when findings are created. Repository and research operations owners make sure those connections survive storage and reuse. And anyone who summarizes, presents or applies a finding shares the job of passing on its scope, source, assumptions and limitations.