Turning Text into Structured Data
Turning text into structured data means coding interviews, comments and open-ended feedback into categories researchers can analyze reliably at scale.

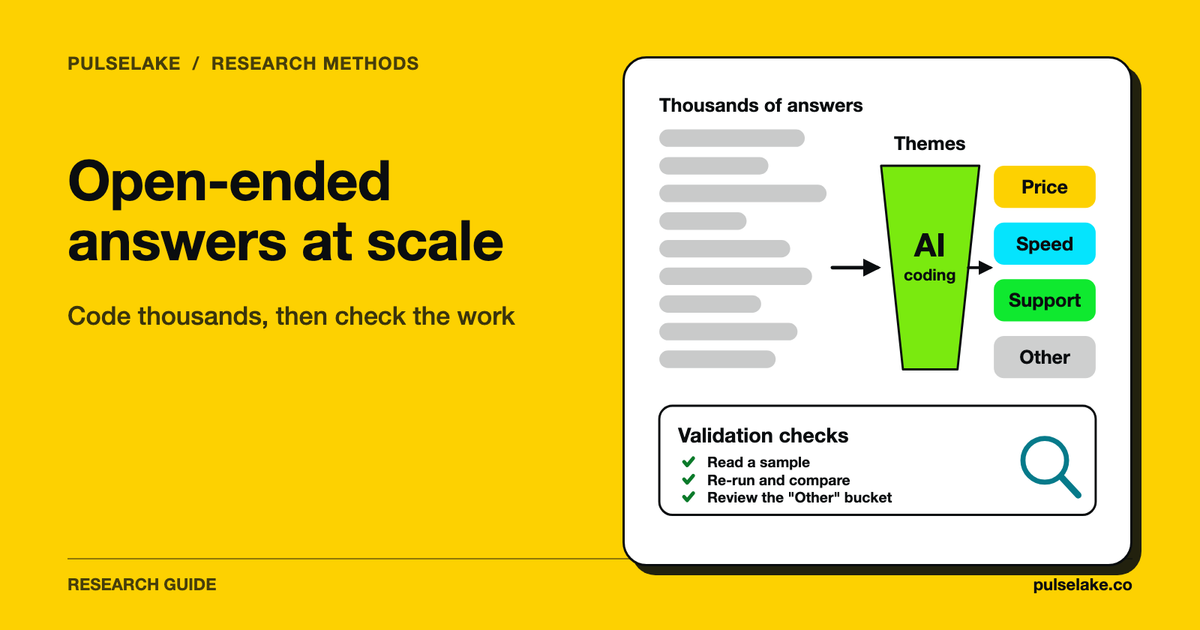
Turning text into structured data means converting unstructured material, like interview transcripts, open-ended comments and feedback, into organized categories, themes and labels you can analyze systematically. The usual name for the process is qualitative coding. It lets researchers compare responses, spot repeated patterns and work through volumes of language that would be hard to summarize reliably any other way.
Research throws off a lot of text, and most of it never gets real analysis. It gets skimmed, quoted selectively and forgotten.
What does it mean to turn text into structured data?
Picture a folder of forty interview transcripts (hypothetical, but familiar). Reading each one alone tells you what that person said. It doesn't tell you how many people said the same thing.
Structuring fixes that. You apply one consistent set of categories or labels to messy language, group similar ideas, and see how often a theme turns up across the whole dataset. The payoff of structured transcript data: interviews you can query, with no rereading.
Nothing says it has to strip out the nuance. A good process keeps the underlying meaning and still lets you ask which concerns come up most, or how a theme differs between two customer segments.
What makes a coding framework reliable?
Two qualities that pull against each other. Flexible enough to catch unexpected insights; consistent enough that different reviewers, or the same reviewer on a different day, put the same text in the same category. Rigid categories miss important new themes. Loose ones make comparisons meaningless.
Documentation is what makes a framework reviewable and defensible. If someone outside the original coding can see how categories were created and applied, they can understand why a piece of text got its label. That matters the moment findings are challenged, or need replicating on new data.
Our blunt view: an undocumented coding framework is one person's opinion with a spreadsheet attached.
How does the coding process work?
It begins with a coding structure: work out which concepts are likely to appear, make categories for them, then assign consistent labels as you read. Coding drops similar ideas expressed in different words into the same group, and those are the patterns you'd never catch reading transcripts one by one.
A typical workflow:
- Read a sample of the text to find recurring concepts.
- Define categories, with clear rules for what belongs in each.
- Apply labels consistently across the full dataset.
- Refine categories when unexpected themes emerge.
- Document how each category was defined and applied.
People skip step five when turning text into structured data. Don't.
And when the volume passes what one person can code by hand? The process has to scale. Finding themes in thousands of responses covers how.

What role does technology play versus human interpretation?
Software handles the boring parts quickly. At scale it helps organize information and surface possible relationships between categories, and it speeds up the mechanical side of coding: sorting, tagging, flagging likely matches for a researcher to confirm.
Interpretation is a separate job. Language carries context, emotion and meaning that plain classification can't fully catch. Someone writes "sure, that's one way to do it." Agreement? Eye-roll? A person reading it in context can usually tell.
To see where automated theme identification adds real value and where a researcher's judgment still has to close the gap, read AI assisted theme extraction.

How PulseLake helps
PulseLake's qualitative analysis agents help organize interview transcripts, open-ended survey responses and other unstructured feedback into consistent categories, while the underlying text and evidence stay linked through the research knowledge graph. That link lets a researcher trace any structured finding back to the original language it came from. Talk to our team to see how this works on a specific dataset.
Frequently asked questions
What is qualitative coding?
Qualitative coding means assigning labels or categories to segments of unstructured text, such as interview transcripts or open-ended survey responses, so similar ideas can be grouped and compared. Language becomes data you can analyze systematically, which one-off reading can't give you.
Does turning text into structured data remove important nuance?
It doesn't have to. Build the coding framework to capture context beside the categories, and keep the original text linked to its assigned codes. Then researchers can go back to the full context whenever a structured pattern needs a closer look.
How much text is needed before structured coding becomes worthwhile?
Less than people think. Even modest volumes benefit, because coding is more consistent than unaided reading, and the advantage grows a lot with volume. Try comparing hundreds or thousands of open-ended responses by hand with no coding framework: it gets impractical fast.
Can the same piece of text belong to more than one category?
Often, yes. One response can reflect several themes, and a well-designed coding framework should allow multiple labels per response when that's what the text says. Forcing everything into exactly one category distorts results whenever responses touch more than one concept.