Annotation Operations for Reliable AI Data
Annotation operations coordinate people, standards, workflows, and quality controls to keep large-scale AI data labeling consistent, efficient, and reliable.

Who assigns the next batch of labels? Who checks it, and who settles a disputed case? Annotation operations cover those arrangements as well as planning, managing and improving the work. Annotators, reviewers and subject matter experts need shared standards, technology and quality controls to keep a growing dataset consistent and traceable. Maintaining that coordination throughout the AI lifecycle is what keeps the data reliable.
Labeling a small batch well is easy. Labeling a huge dataset the same way, with a team that keeps changing, is a management problem.
Quality slips as datasets grow, as people come and go, as edge cases pile up and as research objectives move.
Who is responsible for annotation quality?
Responsibility is shared, but a disagreement should not leave the team guessing who acts next. Distinguish the person labeling the data from the reviewer, the expert who adjudicates a difficult case and the person overseeing operations. That division helps each stage get the attention it needs without confusing responsibilities.
A mature operating model usually has four roles:
- Annotators apply labels under the current guidelines and flag ambiguous cases.
- Reviewers inspect finished work, spot inconsistencies and give structured feedback.
- Subject matter experts settle hard cases that need specialized knowledge or interpretation.
- Operations managers assign work, track progress, monitor workflow health, coordinate updates and improve the process.
A small team may assign more than one of these responsibilities to the same person. Separate job titles are not required. What matters is being explicit about the responsibility at each stage and managing conflicts when roles overlap.
Can your annotators say who approves an exception? If not, they'll quietly invent new rules.
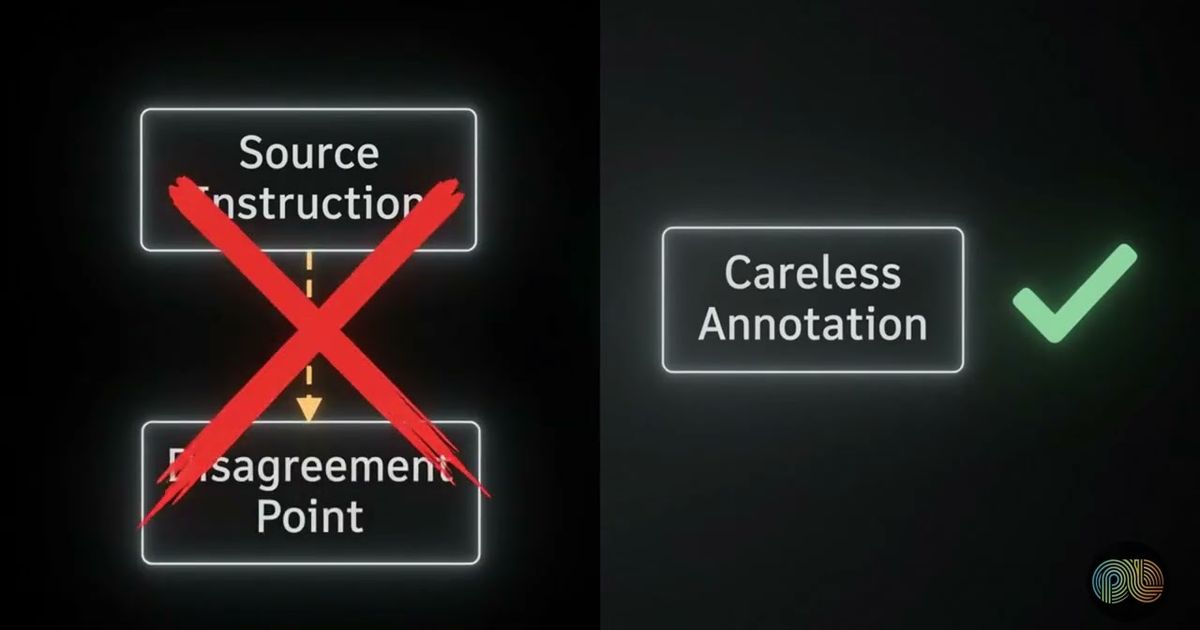
Clear escalation paths make disagreements useful, too. Repeated uncertainty can point to a missing definition, a weak example or a category boundary nobody can apply reliably.

What are annotation operations?
The work continues after an individual labeling task is done. Someone has to maintain the standards, coordinate the next assignments and monitor quality if the data is to remain dependable. Managing those responsibilities over time makes annotation an ongoing capability.
A project needs manageable assignments and annotators trained to interpret the rules consistently. Once work comes back, someone reviews the annotations and resolves disagreements, while the team tracks progress, quality and delays. Definitions and edge cases will change. Keep the guidelines clear, save each version, and record the corresponding dataset version: you need to be able to connect a set of labels to both its rules and its source data.
A finished labeling batch may need another look later in the AI lifecycle. Perhaps the model has changed, the data now serves a different use case, or a previously rare case has become important. Reopening that dataset is easier to manage when the original rules and decisions are still available, rather than having to reconstruct the context.
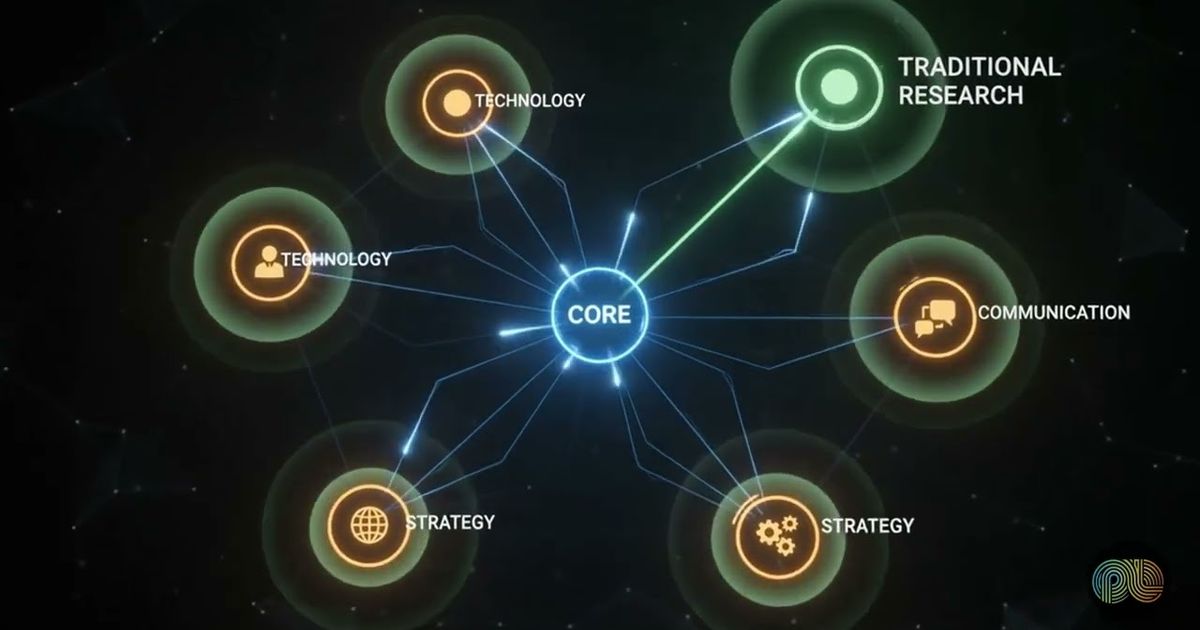
Guidelines sit at the center, and they need active upkeep. Publishing them once doesn't cut it. Effective annotation guidelines define the categories, explain the boundaries, include representative examples and say how to handle uncertain cases.
How can annotation operations improve over time?
Start with a recurring issue in the workflow and investigate why it keeps happening. Change the process in response, then check whether that change actually helped. Keep watching for the next issue. Repeating this work lets the team improve steadily instead of waiting for a dataset to need repair.
Software can assign work, run routine quality checks and track its status. It can also coordinate the workflow: send low-confidence cases for review, require fields to be filled in, record approvals and link dataset versions to guideline versions. Those functions leave the questions of meaning and governance with people. A person must still interpret ambiguous evidence, decide what a label means, approve a consequential change and judge whether the dataset remains suitable for its purpose.
The usual operational mistakes are easy to list. Optimizing for speed alone. Leaving responsibilities vague. Changing guidelines with no version control. Settling disagreements without writing the decision down.
If we had to pick one habit to fix first, it'd be that last one: record who made each decision, which evidence informed it and where the change applies.
Keep doing this as the dataset grows, people leave or join, and research objectives change. Consistent annotation work supports trustworthy AI and reproducible research; keeping its decisions and context also preserves what the organization has learned.
Which annotation operations metrics should teams monitor?
Use agreement, review outcomes, guideline changes and throughput to check the labels and the process producing them. Together they can give warning of trouble before much of the dataset is affected.
For agreement, compare labels assigned independently to comparable material: how often do they match? In the review results, distinguish accepted labels from corrections, rejections and cases sent for further review. Alongside those results, keep the guideline history, including the reason for each change and the dataset versions covered by each rule set. Throughput adds a different view: how much work is getting through, and where is it waiting?
A queue can move quickly because decisions are being rushed, so throughput alone is a poor quality check. Nor does low agreement necessarily mean the annotators are doing a poor job; the instructions may be unclear. Read the measures together and use what reviewers find to adjust training, rewrite guidelines, change task design or improve the escalation procedure.
Watch the trend lines as well. A slow shift in how reviewers read a category may be annotation drift, especially when personnel, source material or objectives change. Catch it early and you can act before the inconsistencies are everywhere.
How PulseLake helps
PulseLake keeps methodology, evidence, decisions, governance and lineage in a persistent study context. Teams can use workflow automation for approvals, QA, notifications and repeatable processes, and an ontology and research knowledge graph help keep reusable definitions and institutional knowledge intact. To talk about how this could support an annotation operating model, talk to our team.
Frequently asked questions
How often should annotation guidelines be updated?
Update a rule when a gap becomes apparent, whether through repeated disagreements, incoming data, a review or a change in objectives. Record the change, its reason and the affected dataset version. Tell annotators and retrain them if it materially changes how they apply labels.
What is the difference between data labeling and annotation operations?
Assigning a category, attribute or other structured information to data is labeling. Operations cover how that work is planned and assigned, how people are trained, and how annotations are reviewed. They also cover escalation to experts, metrics, guideline upkeep and version control, so producing individual annotations stays consistent and sustainable.
Can automation replace human reviewers in annotation workflows?
Only for the routine parts. Automate checks, assignment routing, unusual-pattern flags, version tracking and approval coordination to reduce repetitive work. Keep experts responsible for meaning, governance and final approval. A case needing specialized interpretation or containing ambiguous evidence still requires human judgment, as do guideline changes and consequential quality decisions.